Agentic AI projects stall waiting for clean data when they don’t need to: an agent scoped to one workflow only reads a small slice of your data, and running it in production tells you which gaps in that slice need your attention. George Brown Polytechnic launched a beta agent with an incomplete knowledge base and went from 10% to 82.5% good response rate in less than 90 days.
You don’t need perfect data to launch agentic AI
Part 1 of our blog series Running Agentic AI: The Product Thinking
Author: Zain Ladha
Director of AI & Business Outcomes Consulting
Agentforce and Data360 Practice Lead, leading and training our outcomes strategy team, so that every engagement starts and stays anchored in the customer outcome driving it.
Every agentic project I’ve worked on hits the same question in the first few weeks: is our data good enough for this?
Good news: it almost always is. The bar you’re measuring against is most likely set too high. Whatever you have today is your starting point. You design the agent for the clean final version, to fulfill the ideal process the way you wish it was done, then put it in production early and tune it against what really comes in.
Waiting for data readiness is the first failure mode I’d tell anyone to avoid. The phrase sounds like good diligence, but really, it often serves as an unnecessary stop sign. Companies hear it, look at their knowledge base or their case history, decide they’re not there yet, and push the project out six months. An agent that could have been returning value in January sits in a backlog until July, and the business case moves back down on the priority list.
The cleanup still happens. It happens while the agent runs, prioritized by what your users and customers need, instead of focusing on what a cold audit finds untidy. That reordering is most of the difference between a project that delivers this quarter and one that never quite starts.
We call the tuning model AgentGuard. We built this methodology across one implementation, with a client who had every reason to walk away and didn’t, and is now reaping the benefits of live tuning much quicker than they had anticipated.
What people push back on, every time: usable data can’t be enough, and going live early has to be risky. I’d argue against both, as seen through the story that follows and the six learnings that now drive our approach to agentic.
hero customer story
George Brown Polytechnic with an email-to-case agent
Roughly 70,000 cases a year, no room for new headcount, and a student experience they wanted to fix. We scoped an Agentforce email-to-case agent grounded in their existing Salesforce Knowledge articles. SOW in September 2025, discovery in October, UAT running into the winter semester rush.
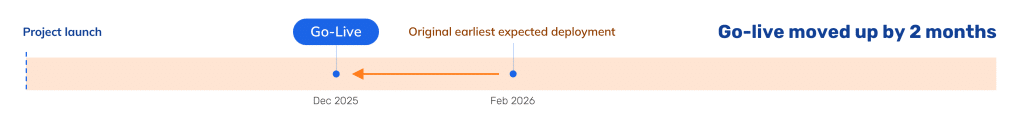
Through development and UAT, the team’s concern was response quality. The agent was saying things that could affect revenue and student sentiment, and the content was off often enough that a CSR wouldn’t have sent it. Go-live was scheduled for February. We launched in December instead, two months early, with a clear improvement plan in place.
1. Waiting for clean data is the most expensive decision in the project
Funding the audit first can feel like the logical order: governance gets stood up, ownership gets chased across systems that have never spoken to each other, years of history get back-filled, CRM fields get reviewed. The spend starts well before the agent does any work, and the enthusiasm that funded it, the resources and the time allowed to the initiative usually run out before the cleanup is completed. And that’s before counting the delay: running cleanup and tuning as two sequential projects instead of one pushes real business impact out by months.
In many of those cases, nobody can really tell what fully clean data looks like. Is it a percentage, a number of records, a date, a clear set of data owners? The target moves every time someone finds a new way the agent could be wrong, and there is always another way.
Data cleanup belongs inside the implementation. Run the agent, and it tells you which gaps are costing you, in the order your customers hit them. That’s the most cost effective way you’ll make your data ready for AI agents with the highest return potential.
For George Brown Polytechnic
The belief that the knowledge base had to be fixed before the agent could be trusted was reasonable. It was also going to cost them another three months minimum, through their busiest intake period, with nobody able to say what would make it good enough to stop. Instead, we aimed for the shortest path to real value. Both sides came to the same read: tuning against live cases would teach us more, faster, than continuing to guess how the agent would behave in scenarios we had only imagined.
2. Every week spent perfecting the agent is a week your team works the old way
Delay has a price that goes beyond just the invoice
- Credibility with your team and your board. A project approved as proof that agents deliver turns into a data cleanup program. Everyone who signed off now owns a different project than the one they approved.
- Budget against a target nobody defined. Money moves steadily toward a finish line that keeps relocating. There’s always one more field, one more system to reconcile, one more edge case someone raised in a workshop. Spend keeps accumulating with no final checkpoint in sight.
- The value the agent would already be producing. Whatever the agent handles well today, it handles well today. Every week it stays in a test environment, that capacity goes unused. An agent answering reliably on half its cases is saving your team real hours on half its cases. Holding it until it manages the rest means paying for both halves and using neither.
Two ways leaders handle this
Some look at an agent performing at 50% and see the half that fails. They keep it in testing until it covers every case they can imagine, and the working half waits on the shelf for months. When the agent finally launches and still gets things wrong, leadership reads that as proof the whole approach was flawed, and the next AI initiative gets even harder to fund.
Others look at the same 50% and see half their team already moving faster. They tell their people the agent is learning, put it somewhere its mistakes can’t reach a customer, and let real cases show them what to fix.
The second approach is our new standard, and it’s the way we’ve implemented agentic in our own operations. You simply need to put an agent in production without exposing the business during the initial tuning phase.
For George Brown Polytechnic
Through the fall and early winter, the Contact Centre and Domestic Admissions teams answered routine inquiries by hand, one at a time, at the busiest point of their intake year. They were short-staffed and working through a labour strike.
The capacity problem they had brought to us was still entirely theirs, and the agent built to relieve it was sitting in a test environment answering nobody. Both sides were burning time and money trying to perfect the agent before anyone could use it, and each week of additional testing pushed real value further out. On the trajectory they were on, a release was looking like February at the earliest.
Every company running these projects was hitting the same wall, at the same stage, for the same reasons. That made it easier to say out loud that the sequence was the problem, not the client’s data. GBP and Diabsolut were trying to make the thing perfect, when we needed to treat the AI and the data like a product instead of a project, and that’s what we did.
3. An agent that can’t reach your customer can go live much sooner
Choose to go live early, on purpose, without exposure
Going live early is a decision you make while the agent is still rough. The exposure people fear comes from the engineering choice of where to put the agent.
Put it behind your team instead of in front of your customer. The agent reads the incoming request, drafts a response, and hands it to the person who would have written it. They review, edit if needed, and send. Nothing it gets wrong reaches anyone outside.
That arrangement pays twice. Your team gets faster on every good draft starting day one, which is value while the tuning is still happening. And every rejected draft is a data point from a real case instead of being hypothetical, carrying a reason written by the person best placed to judge it.
Standing up an agent this way is the governed part of the work: the process it joins already functions, the data connected to it is good enough to act on, and there is an agent charter setting the guardrails, named owners, and a human reading every output before anyone outside sees it. Do that and you’re in production months earlier, with no path for a bad answer to reach a customer.
It also gets you about 40% of the way to an agent you’d trust, in only a few weeks. The rest comes from tuning, once real cases start arriving.
40% of an AI agent’s performance comes from how you build it before the governed launch. The other 60% comes from tuning it against real scenarios.
For George Brown Polytechnic
We made the proposal the week after they told us they didn’t trust the agent. Go-live was booked for February. We asked them to launch two months early instead. The argument was that UAT would keep producing hypothetical edge cases indefinitely, and only production would tell us which ones were real. The conversation went both ways: here’s what we’re changing, here’s what we need from your team, and we’re investing in you to make it work. They agreed to try it our way.
Instead of emailing the student, the agent would stamp its draft onto the case, and a CSR would read it before anything went out. Good draft: copy, paste, send, with no article hunting and no writing from scratch. Weak draft: specific feedback on why, from the person who would have had to send it.
They went live internally at the end of December 2025.
4. Only risk and access problems have to be solved before launch
Deciding to go live early changes the question from “is the data clean” to “what would actually make this unsafe.” That list is short, and it isn’t about data quality. Split the problems: things that must be true before launch vs. things only usage will reveal.
Four things block a launch:
- Unclear permissions: The agent can reach a system nobody meant to expose
- No escalation path: No follow-up action gets triggered when it can’t answer
- No owner: No one owns the agent once it’s running
- Sensitive workflows: It handles a task where a wrong answer costs money or trust, with no defined governance in place
Everything else people classify as not ready is discoverable in production: missing articles, duplicate records, weak categorization, content that reads fine to a person and confuses an agent. Those get found faster in production than in an audit, because real cases arrive in priority order. An audit hands you every problem at once with no ranking. A week of live traffic hands you the ones customers hit.
Scope distinction: ready for what, ready for whom
An agent scoped to one workflow in one team reads a narrow slice of what you own. Whatever state the rest of your data is in, that slice is the only part it touches. So “is our data ready” is the wrong question. Answer these two instead: which workflow is the priority use case, and which users will the agent serve.
Narrowing the scope shrinks the blocker list too. Every workflow you keep the agent out of is a risk you don’t have to govern before launch.
For George Brown Polytechnic
Anything touching revenue, billing, or registration was routed away from the agent entirely, straight to a human, because those categories were where a wrong answer carried real consequences. That decision came directly out of what UAT had exposed. Scope stayed where it started: email-to-case, low and medium complexity, existing Knowledge articles, two departments out of nine.
Nobody audited the knowledge base before launch.
5. Your charter sets the target, weekly tuning gets the agent there
Once you’re live, weekly improvement needs a reference, if you don’t want every review to be based off your team’s opinion. Someone thinks the answer was too long, someone else thinks it missed the point, and the changes you make depend on who spoke loudest.
The reference is the agent charter, written at the start of the project, in plain business language, with no technical spec: what the agent is for, what goes in and what comes out, the business and technical measures it answers to, its guardrails, and the sources it can draw on. Each week’s analysis compares what the agent did against that document, so a gap list can emerge from the reviews.
AgentGuard: Diabsolut’s methodology for agent optimization
AgentGuard™ targets the 60% of performance that only live usage can teach the agent. It runs on a weekly cycle. Production behaviour comes in, and five elements come out:
- Optimize the agent based on what happened, using real cases
- Improve the data, targeted at the gaps production exposed
- Train the people prompting or reviewing it, since their inputs shape what the agent returns
- Disclose technical limitations, so you stop expecting what the agent can’t do yet
- Review the report: what shipped, why, who owns what’s next, and what to expect from it
Every finding belongs to one of four categories. The data. The agent. User behaviour. Or a known technical limit you disclose. That fourth category will keep adoption intact, because a user who knows the boundary stops testing it. The first three get worked through until quality and consistency are achieved to the level you had set out for.
Assess the agent over a quarter, the way you’d coach a new hire over their first few months. You wouldn’t cut a trainee loose after one good week, or write them off after one bad one, and your agents deserve the same.
For George Brown Polytechnic
We configured a review process quickly, so the CSR team could rate the agent’s output and comment on it directly from the case they were working.
The rating had four options, running from send as-is down to would never send. Anything below sendable required a written explanation. A validation rule kept the case from closing until someone filled it in, which meant the feedback kept arriving even through their busiest weeks. By the end of the refinement period we had hundreds of reviewed cases to work from.
Response quality started under 10%. By day 70 it had reached 82.5%, measured by whether a CSR would send the draft without changing a word. We ran three more weeks after that to confirm the number held.
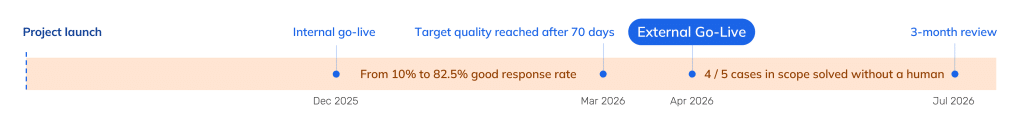
After the internal period confirmed the quality held, we took the agent offline to reconfigure it for students, ran regression testing, and deployed. About seven business days. It went live externally on April 18, 2026, answering student emails directly.
In its first three months, it handled 6,433 cases. Combining what it closed and what it routed correctly, 89% of that volume moved through without a human needing to triage it first.
6. Your agent will find data problems your team swears don’t exist
Run the agent and it produces a list of your data problems in priority order, because the ones that surface first are the ones your customers are actually hitting most often. Three kinds show up.
- Missing content
Experienced people will tell you an article covers something because they’ve answered that question fifty times. The article lives in their heads, and nobody noticed because the workaround has been running for years. - Contradictory content
An article nobody archived sits beside its replacement. The agent reads both, finds relevant material in each, and merges them into an answer that’s half right. - Unreachable content
The article exists and is accurate. Chunking, data categories, or wording keep the agent from finding it when someone asks in their own words.
What comes out of this is a cleanup list you can work through in priority order, built from what your customers ask, without having to preemptively build a full inventory of what’s untidy. The agent becomes the fastest data-quality diagnostic you have.
For George Brown Polytechnic
Between 30 and 40% of the negative feedback CSRs gave the agent turned out to be missing articles. The reps were certain the content existed, because they’d been answering those questions for years. Their knowledge manager, sitting in the same weekly review, was the only person who could confirm it didn’t. Without her in the room, those cases would have been logged as agent failures and answered by adjusting prompts that were never the problem.
The conflicting articles were harder to see. An old version and its replacement each held part of the right answer, so the agent stitched them into a response that no single source explained. The weekly analysis surfaced both sources side by side, which is how their knowledge manager learned that two of her own articles could collide. She split the content, rewrote the subject lines, and corrected the data categories so the pairing wouldn’t repeat.
Retrieval failures took the longest to identify. Current, accurate articles stayed invisible because of how they’d been chunked and categorized. Each fix was small on its own. Finding them meant comparing what the agent pulled against everything it could have pulled, every week for three months.
George Brown owned every one of those fixes. The knowledge base improved while the agent was running, and both improved together.
You can start this quarter with what you already have
Five things get you to a governed launch
- One workflow worth automating
- A set of sources you trust enough to act on
- A human between the agent and your customer
- A weekly cadence with people who can approve changes
- Someone who owns the fixes the agent surfaces
That’s the list. Everything else on your data readiness plan can happen while the agent runs, paid for by the value it’s already producing.
Ready to take action?
Find out what your data is already good enough for
Tell us the process costing your team the most time right now. We’ll walk through what a governed launch would take, which parts of your data it would touch, and what the first 90 days would realistically look like.
This article is part of our blog series
Running Agentic AI: The Product Thinking
- Part 1: You don’t need perfect data to launch agentic AI
- Part 2: Your AI agent is only as good as the people who own it
- Part 3: A deliberately small first AI agent beats a too ambitious scope (Coming soon)
- Part 4: Measure your AI agents’ performance the way you’d assess a new hire (Coming soon)
- Part 5: Automate your data hygiene: Let the agent fix what the agent found (Coming soon)